Quick answer: Measure AI-augmented teams on output quality, turnaround speed and business impact rather than hours logged. When AI cuts a four-hour task to forty minutes, time-based metrics stop meaning anything. The practical replacements are volume completed, error and rework rates, cycle time and the value of work shifted to higher-priority tasks.
Most SMEs did not choose hours as a metric; they inherited it. It survives because it is easy to collect and feels like control. AI breaks it, quietly, and the businesses that keep steering by it end up managing the appearance of effort while the actual gains go unmeasured and unclaimed.
Why are hours logged the wrong KPI for AI-augmented work?
Because hours measure input, and AI changes the relationship between input and output so drastically that the input number stops carrying information. Three failures, specifically:
- It punishes the behaviour you want. A team member who redesigns a workflow so a report takes forty minutes instead of four hours shows up in a timesheet as doing less work, when they have just done the most valuable work of the quarter
- It hides the gains. If capacity freed by AI is reabsorbed invisibly, the business pays for a productivity improvement it never sees. Freed hours should be a tracked number with a destination
- It says nothing about quality. AI makes output fast by default; whether it is right is the question that matters, and hours logged cannot answer it
None of this means time disappears from measurement. Cycle time, the elapsed time from request to delivered output, becomes more important, not less. What dies is effort-time: hours at the desk as a proxy for value.
What KPIs should replace time-based metrics for an AI-augmented team?
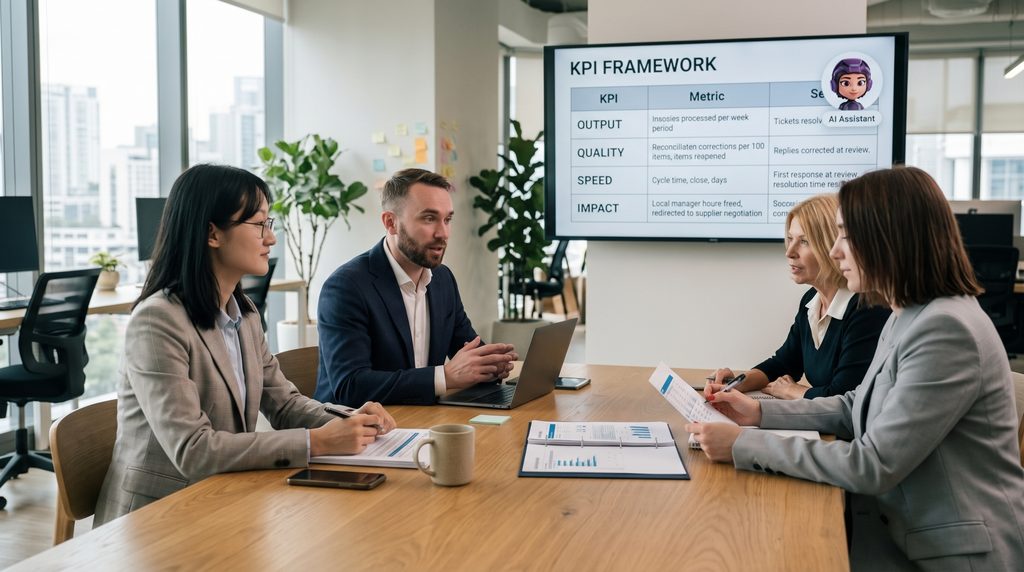
Four families, covering output, quality, speed and impact. Here is the framework with worked examples for a typical offshore seat:
| KPI family | Metric | Example (accounts seat) | Example (support seat) |
|---|---|---|---|
| Output | Volume completed per period | Invoices processed per week | Tickets resolved per week |
| Quality | Error rate and rework rate | Reconciliation corrections per 100 items; items reopened | Replies corrected at review; |
| Speed | Cycle time, request to delivery | Month-end close, days | First response and full resolution times |
| Impact | Hours returned and where they went | Local manager hours freed, redirected to supplier negotiation | Senior staff hours freed, redirected to complex accounts |
Two rules make the framework honest. First, every metric needs a pre-AI baseline captured before the workflow changes; a number without a baseline is a brag, not a measurement. Second, the impact row must name a destination for freed hours. ‘We saved 15 hours a week’ is only half a result until it becomes ‘and they went to client-facing work’.
How do I benchmark AI-assisted output?
Benchmark the output of your AI-augmented team against your own baseline first, peers second, and vendor claims never. The sequence:
- Baseline (week 0): measure the workflow as it runs today: volume, error rate, cycle time, hours consumed. One ordinary fortnight of data is enough
- Trend (months 1-3): track the same four numbers fortnightly. Expect a dip during transition, then a climb that continues as prompts and templates improve; a flat line after month two means the workflow was bolted on rather than redesigned
- External reference (quarter 2 onward): once your trend is stable, compare against published figures from named sources for similar workflows, treating them as direction rather than targets, since definitions vary
Review the numbers fortnightly for the first two months, monthly after. The fortnightly rhythm matters early because it catches the most common failure, quality drifting while volume climbs, while it is still a tuning problem rather than a client problem.
What this means for how you manage
Managing an AI-augmented team with modern metrics changes the conversation. Weekly check-ins stop being about activity and start being about exceptions, blockers and the next workflow worth redesigning, which is also a far better conversation to have with a remote team than ‘what did you do today’.
This framework is how Hyvid reports on every engagement by default: baseline first, then fortnightly output, quality, speed and impact numbers your manager can read in a minute. If you want to see what that reporting looks like on a live seat, see how Hyvid reports performance.
Frequently asked questions
Across four KPI families: output (volume completed), quality (error and rework rates), speed (cycle time) and impact (hours returned and their destination), each against a pre-AI baseline, reviewed fortnightly at first.
Because AI breaks the link between time spent and value produced. Hours punish efficiency, hide the gains and say nothing about quality; cycle time and output metrics carry the information hours used to pretend to.
Cycle time measures how long the business waits for a result, from request to delivery. Hours logged measure how long a person sat with the task. AI collapses the second while making the first your real competitive number.
Capture your own baseline before the workflow changes, trend the same metrics fortnightly, and only then compare against published external figures as a direction check. Never benchmark against tool vendors’ marketing claims.
That is the framework working: it has caught over-trust in unreviewed output early. Tighten the review tier on the affected workflow, feed the recurring corrections back into prompts and templates, and expect the error rate to fall within a fortnight.